How to Export Data from SQL Server to Excel
Download the free 14-day trial for the SQL Spreads Excel Add-in if you want to easily let your non-technical users update and manage SQL Server data from Excel.
In a previous article, SQL and Excel: Why you need both , we showed that for many businesses the use of both SQL Server and Excel is an optimum approach to data management. For organizations that use SQL Server and Excel extensively, there is often a need to export data from SQL Server to Excel. The most common reasons to get the data into Excel are to:
- produce data visualizations such as charts and graphs for use in reports
- aggregate or analyze data in pivot charts
- collate data from multiple sources for further transformation
- make the data available to non-database users to view or process
In this article, we’re going to look at how to export data from SQL Server to Excel. The first method uses the SQL Server Import and Export Wizard, which can be used to export data to a number of destination types, not just Excel. The second method uses native functionality in Excel. The third method uses the SQL Spreads Add-In for Excel, which provides functionality beyond the export process. There are pros and cons of each method, which we’ll summarise at the end of the article.
Table of contents
- 1. Method (1): Exporting using SQL Server Import and Export Wizard
- 2. Method (2): Exporting using native functionality in Excel
- 3. Method (3): Exporting using SQL Spreads Add-In for Excel
- 4. Summary
Method (1): Exporting using SQL Server Import and Export Wizard
The SQL Server Import and Export Wizard can be launched from within SQL Server Management Studio or as a stand-alone application.
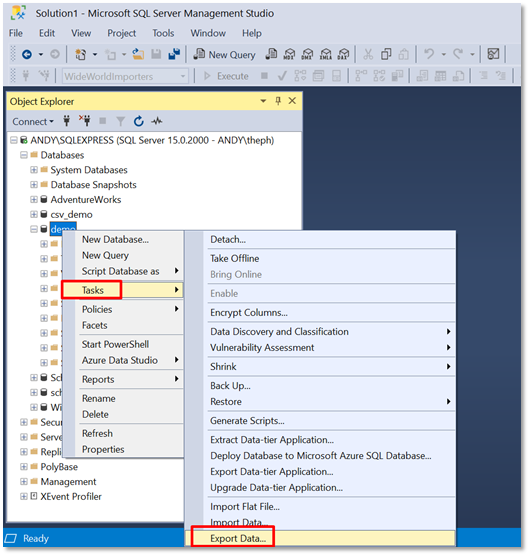
From within SQL Server Management Studio, click on the database from which you want to export data. We’re using the demo database in our example, so click on that and then right-click and select Tasks > Export Data.
The Welcome page is displayed, and you can go ahead and click ‘Next’.
On the next screen, select the data source. To export from SQL Server, select ‘SQL Server Native Client’.
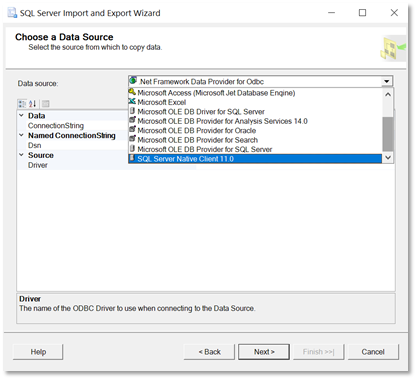
Once you’ve selected ‘SQL Server Native Client’, the details about the data source will be populated by the wizard.
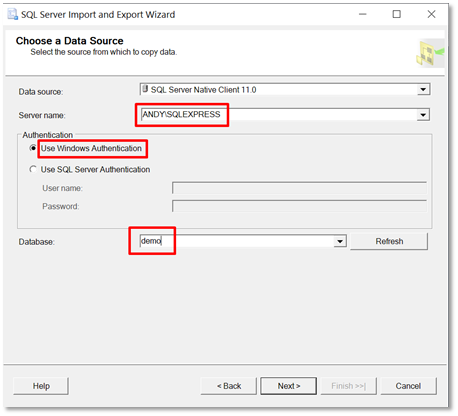
Click ‘Next’ to go to the next screen, where you going to choose the destination for the export, which for us is Excel.
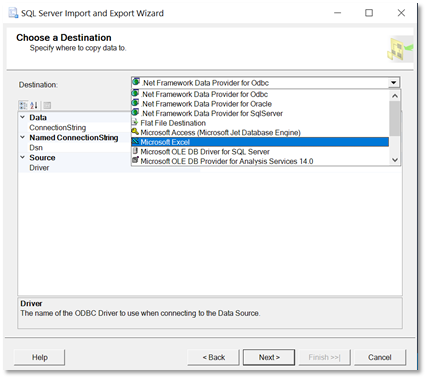
When you select Excel as the choice of destination, you then need to provide the location of the Excel file. When you then click ‘Next’, you may see the following message:
The operation could not be completed.
ADDITIONAL INFORMATION:
The ‘Microsoft.ACE.OLEDB.16.0’ provider is not registered on the local machine. (System.Data)
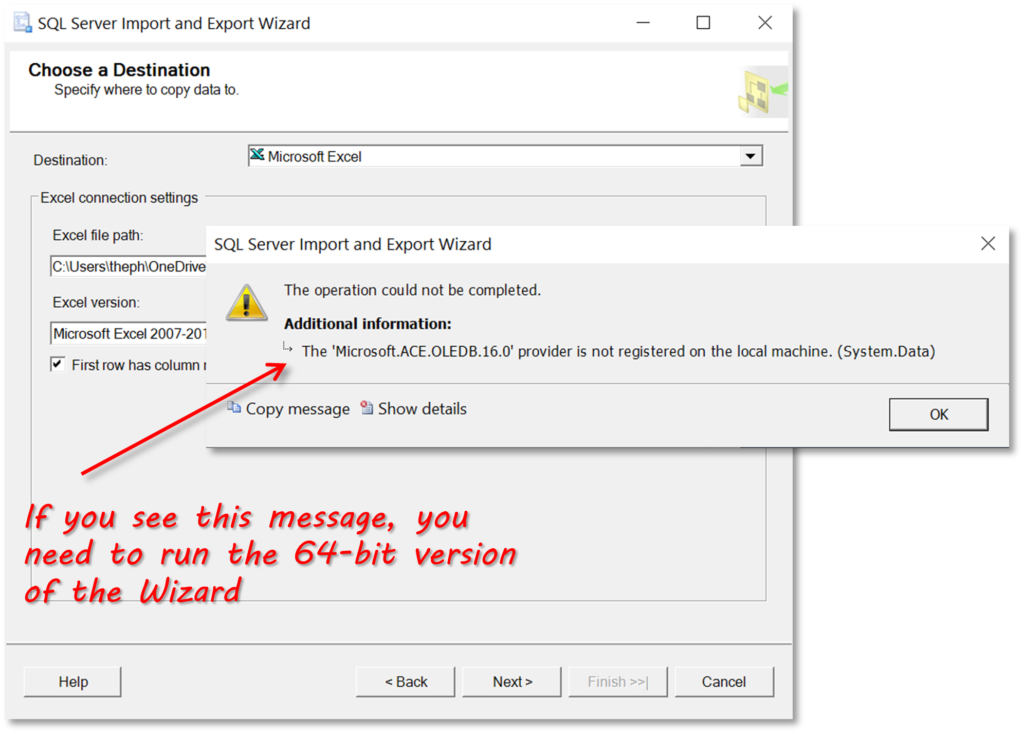
The reason this message appears is that when you launch the SQL Server Import and Export Wizard from SSMS, a 32-bit version of the wizard is launched (because SSMS is 32-bit) and your operating system is 64-bit. There is more information on this here .
To get around this, you need to close SSMS and go to the Windows Start menu and search for the 64-bit version of the SQL Server Import and Export Wizard from the Start menu. Note that this version will only be installed on your computer if you have installed SQL Server.
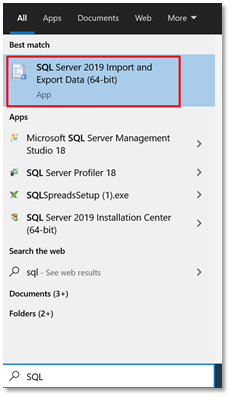
Once the stand-alone version of the Wizard has started, you can go through the steps as discussed so far, which was to specify the source and destination of the data copy. We now need to define what we want to copy, and (optionally) configure the copy operation.
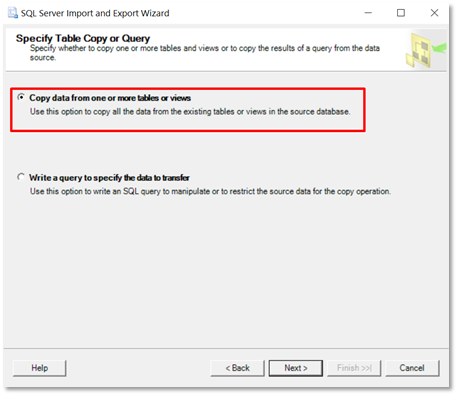
After clicking ‘Next’ on the ‘Choose a Destination’ screen, you specify whether you want to export one or more complete tables or views, or a subset of data via a SQL query. In our case, we are exporting from a single table, so we can leave the default option selected.
Next, we’re going to edit the column mappings by clicking the ‘Edit Mappings…’ button. The Column Mappings screen allows you to make changes to the name and data type of the columns that will be created in Excel by the copy operation. In our example, we’re going to change the data type for the ‘order_date’ column from VarChar to DateTime. We’ll leave the others as the default set by the wizard. Click ‘Next’. The next screen in the wizard summarizes that the source is a SQL table called sales and the destination will be to a sheet called ‘sales’ in the Excel workbook. You can change the name of the sheet as needed.
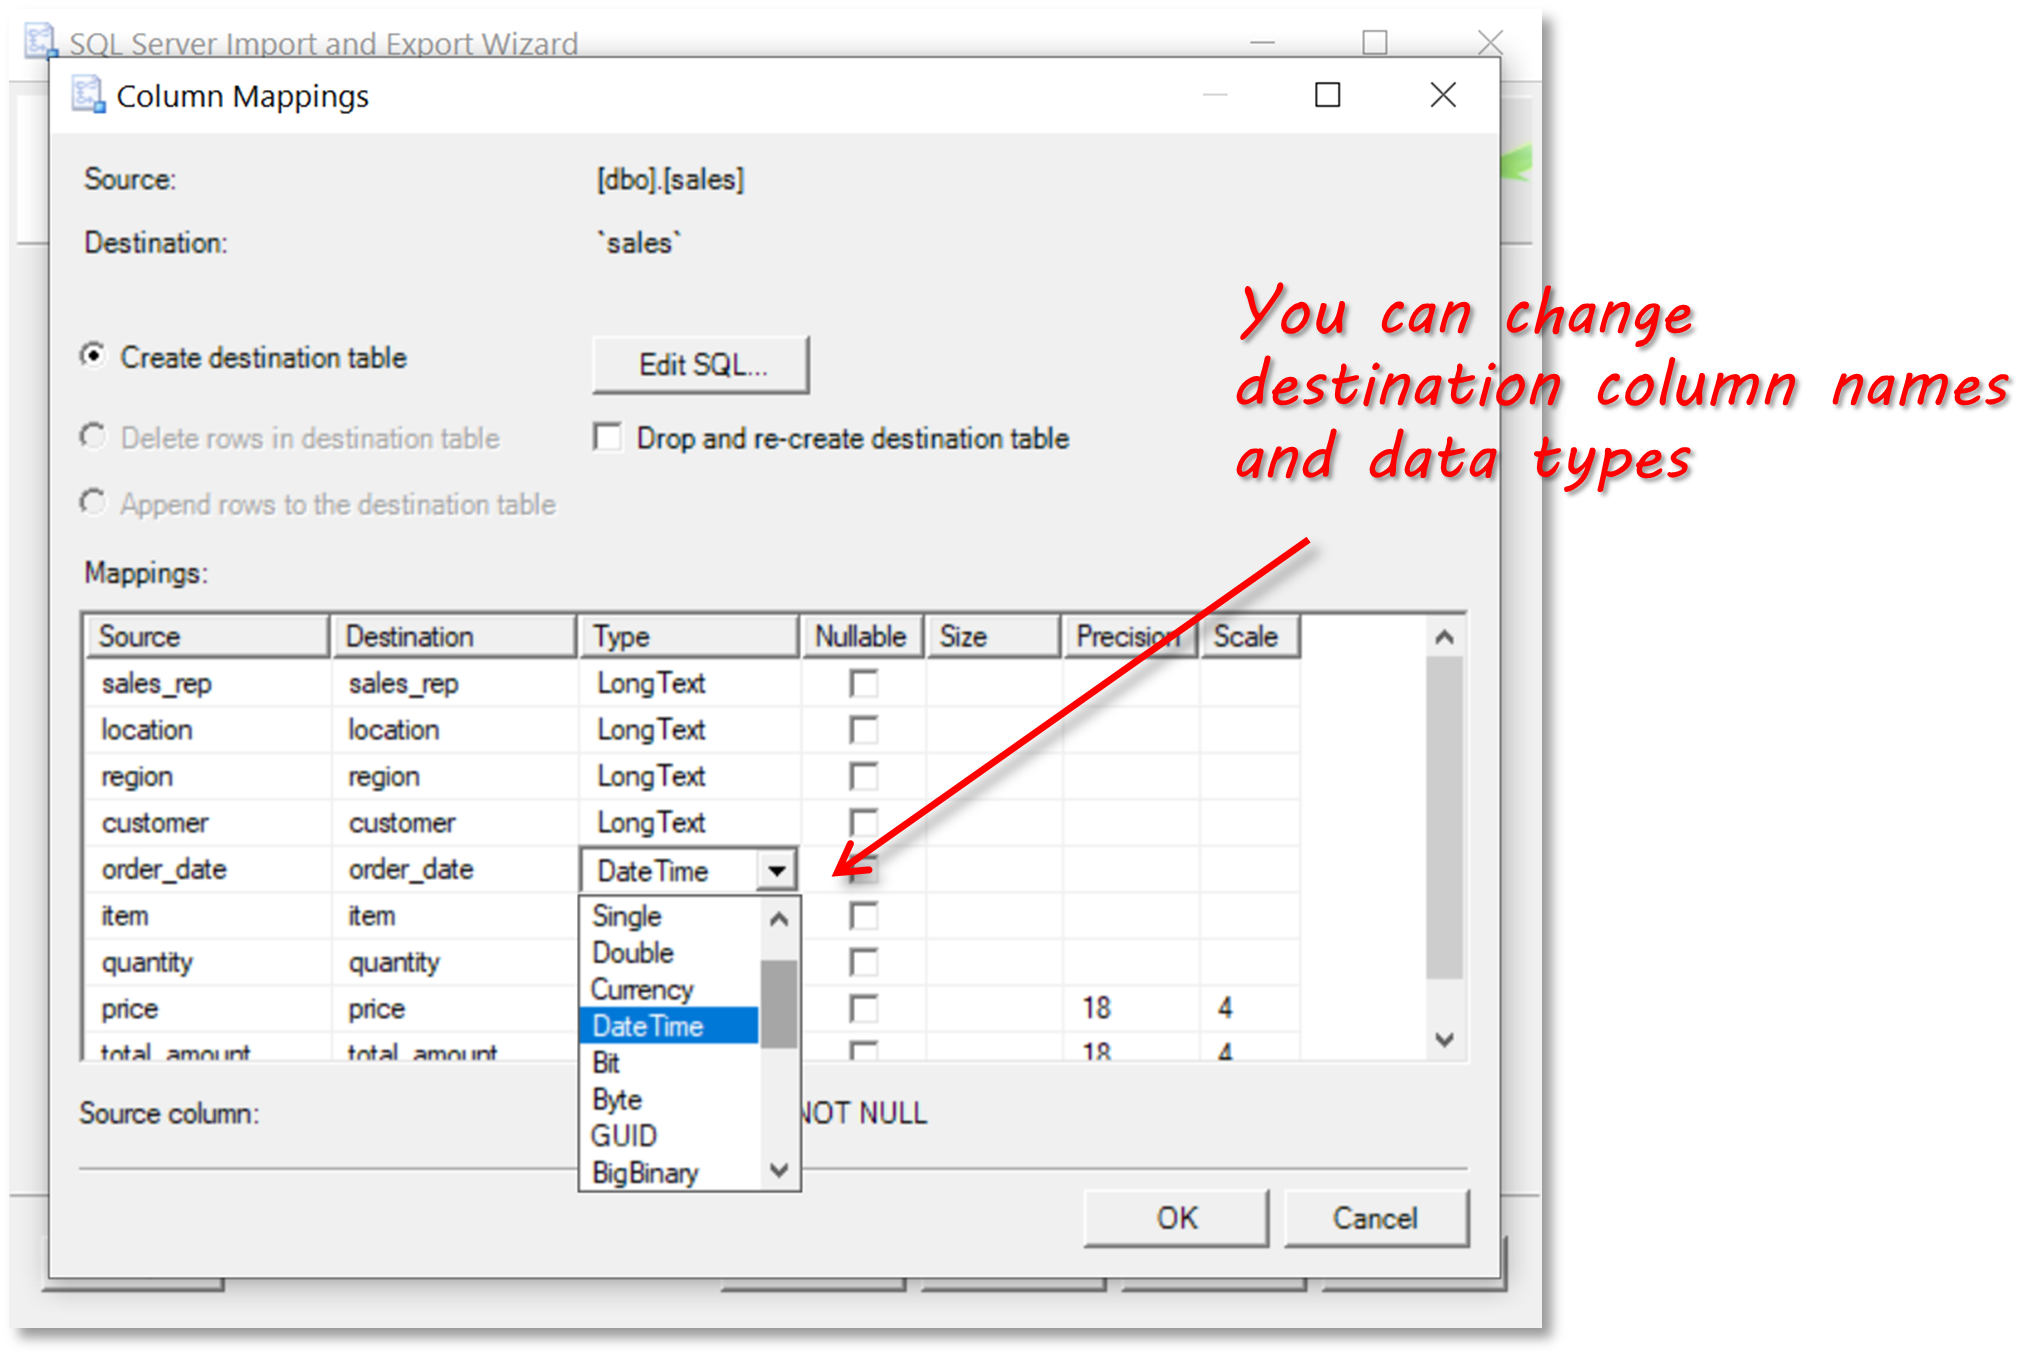
Once done, click ‘Ok’ to close the dialog and then ‘Next’.
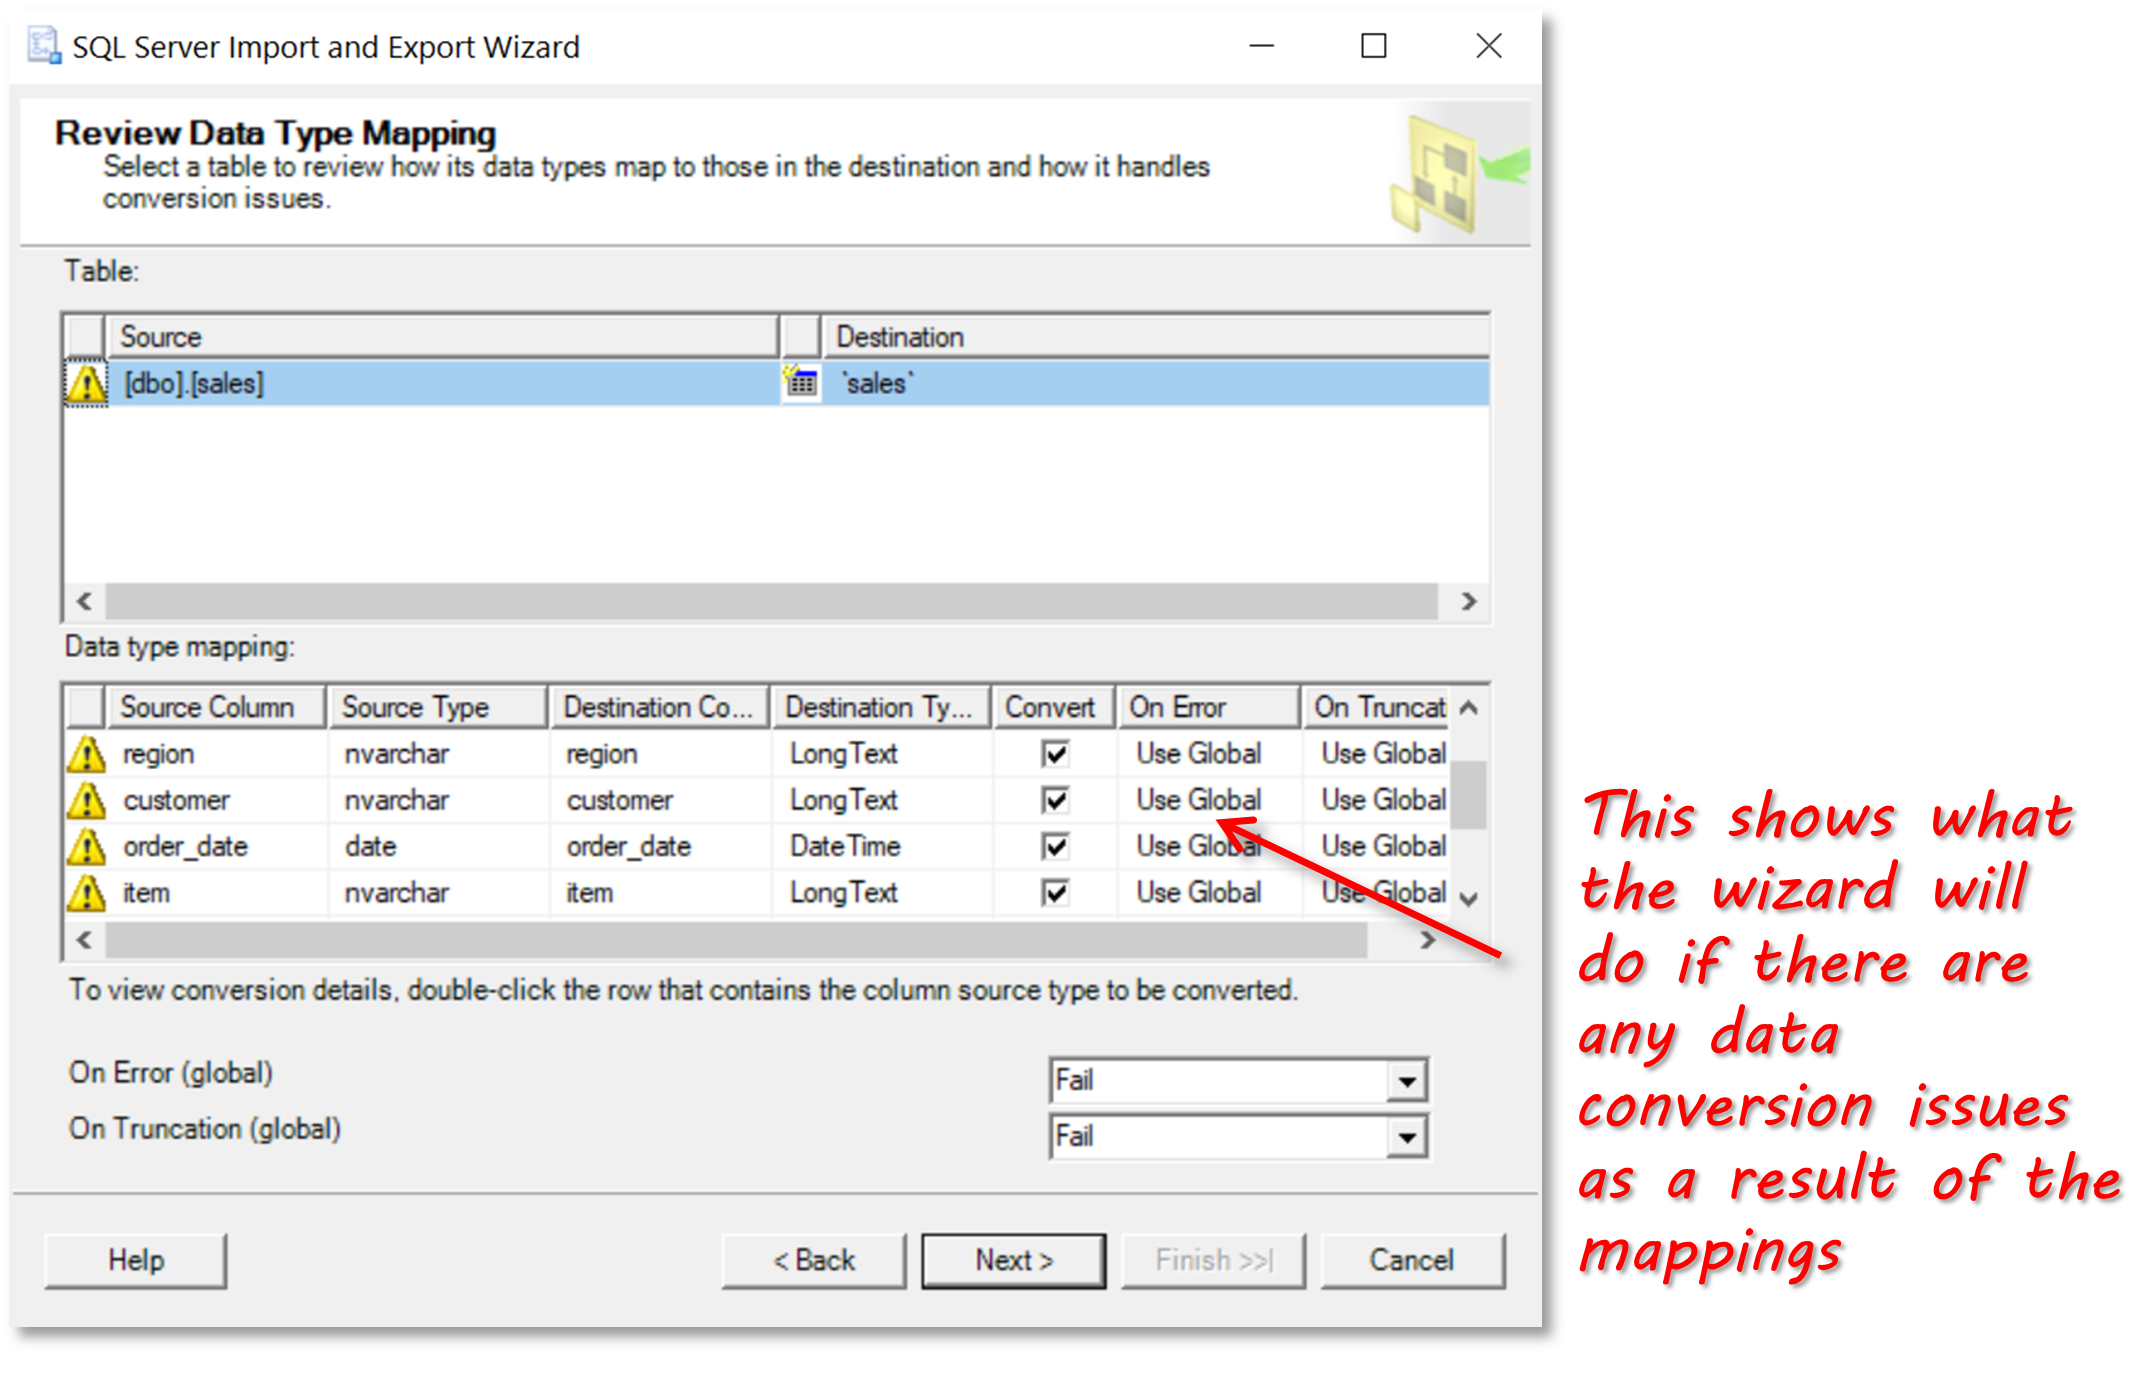
If any of the mappings that we specified may not succeed in the export process the SQL Server Import and Export Wizard shows the Review Data Type Mapping page. This page will highlight the conversions that the wizard needs to perform to handle the mappings that you have specified. It also indicates what the wizard will do if a there is an error during the conversion. It can either ignore the error or cause the export to fail. In our example, several columns have been flagged: the ones where there is a conversion from nvarchar(max) to its Excel equivalent, Long Text, and also the conversion from VarChar to DateTime for the ‘order_date’ column. The default setting is for the wizard to fail if there is an error, so we’ll leave that option in place.
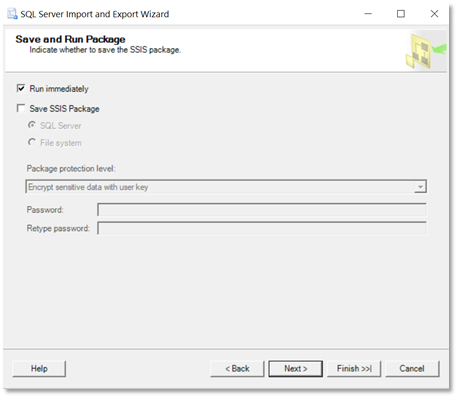
Note: This SQL Import and Export Wizard uses SSIS under the hood; in other words, each time you run the wizard, you are creating an SSIS package. This is why you are given the option of saving it for future use.Click ‘Next’. The wizard now offers you the chance to save the Wizard configuration as an SSIS package in addition to the default option of running the copy immediately.
We are just going to leave the default option ticked and then click the ‘Next’ button.
The wizard now displays a summary of the steps that we have configured.
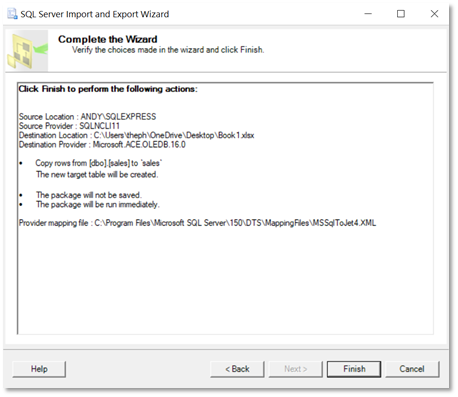
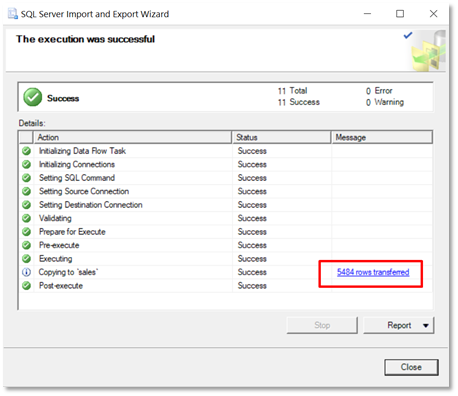
Click ‘Finish’, and the wizard will now show the final screen, which is the result of the execution. In our case, the execution was successful, and we can see that 5484 records were copied to the ‘Query’ sheet in our Excel workbook.
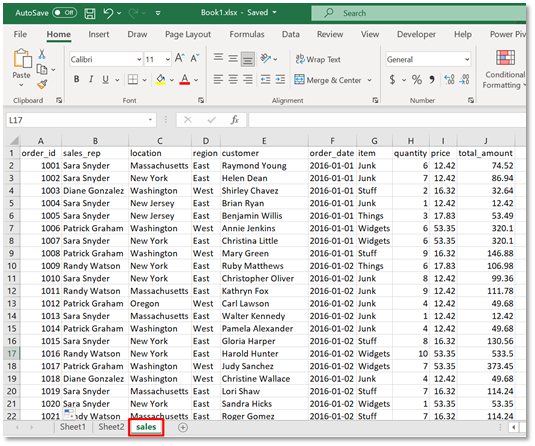
We can check that the data has been exported from SQL Server to Excel by opening up the file that we specified and checking the ‘sales’ sheet.
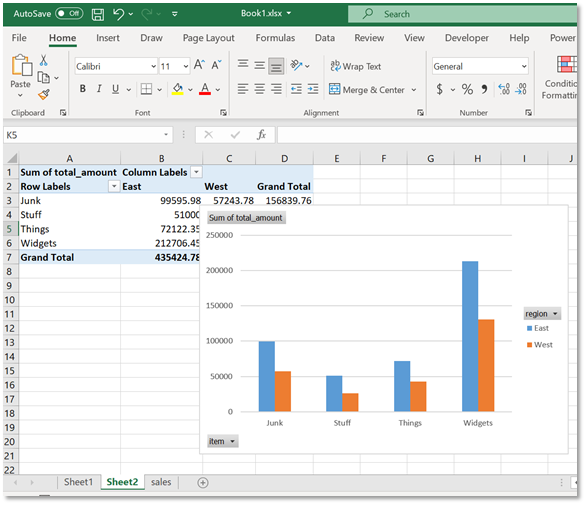
Now that the data is in Excel, we can create some visualizations or aggregations, or whatever other processing we want to perform. For example, we could create a pivot chart to display the Total per item per region.
Method (2): Exporting using native functionality in Excel
Although the method itself is much the same, Microsoft has made improvements in the last few releases to the way you get data from other sources into Excel. The main change was the addition of the Power Query data import wizards and tools as a native component in Excel 2016. These are accessed from the Power Query Editor, although it’s not displayed as such on the Excel Ribbon – instead, it is branded as Get & Transform Data group on the Data tab of the Excel ribbon.
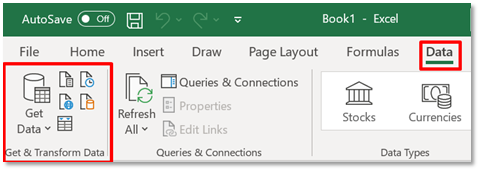
The steps described below are valid for Excel 2016 and beyond.
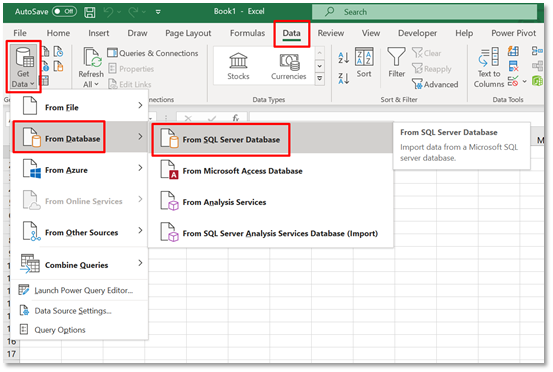
To get started with the export from SQL Server to Excel, click on Data > Get Data > From Database > From SQL Server Database.
You are next prompted to enter the database server to connect to and, optionally, specify a database. If you don’t specify a database, you can select from the available ones on the next screen.
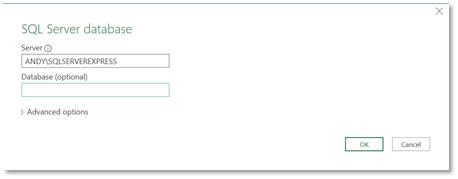
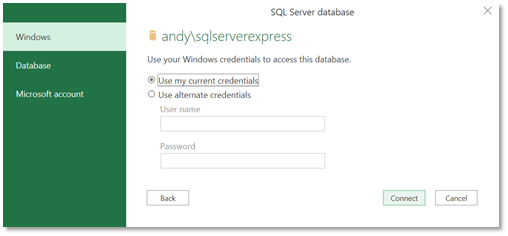
Click ‘Ok’. You’ll then be prompted to provide authentication details. The default is Windows, so you can go ahead and click ‘Connect’.
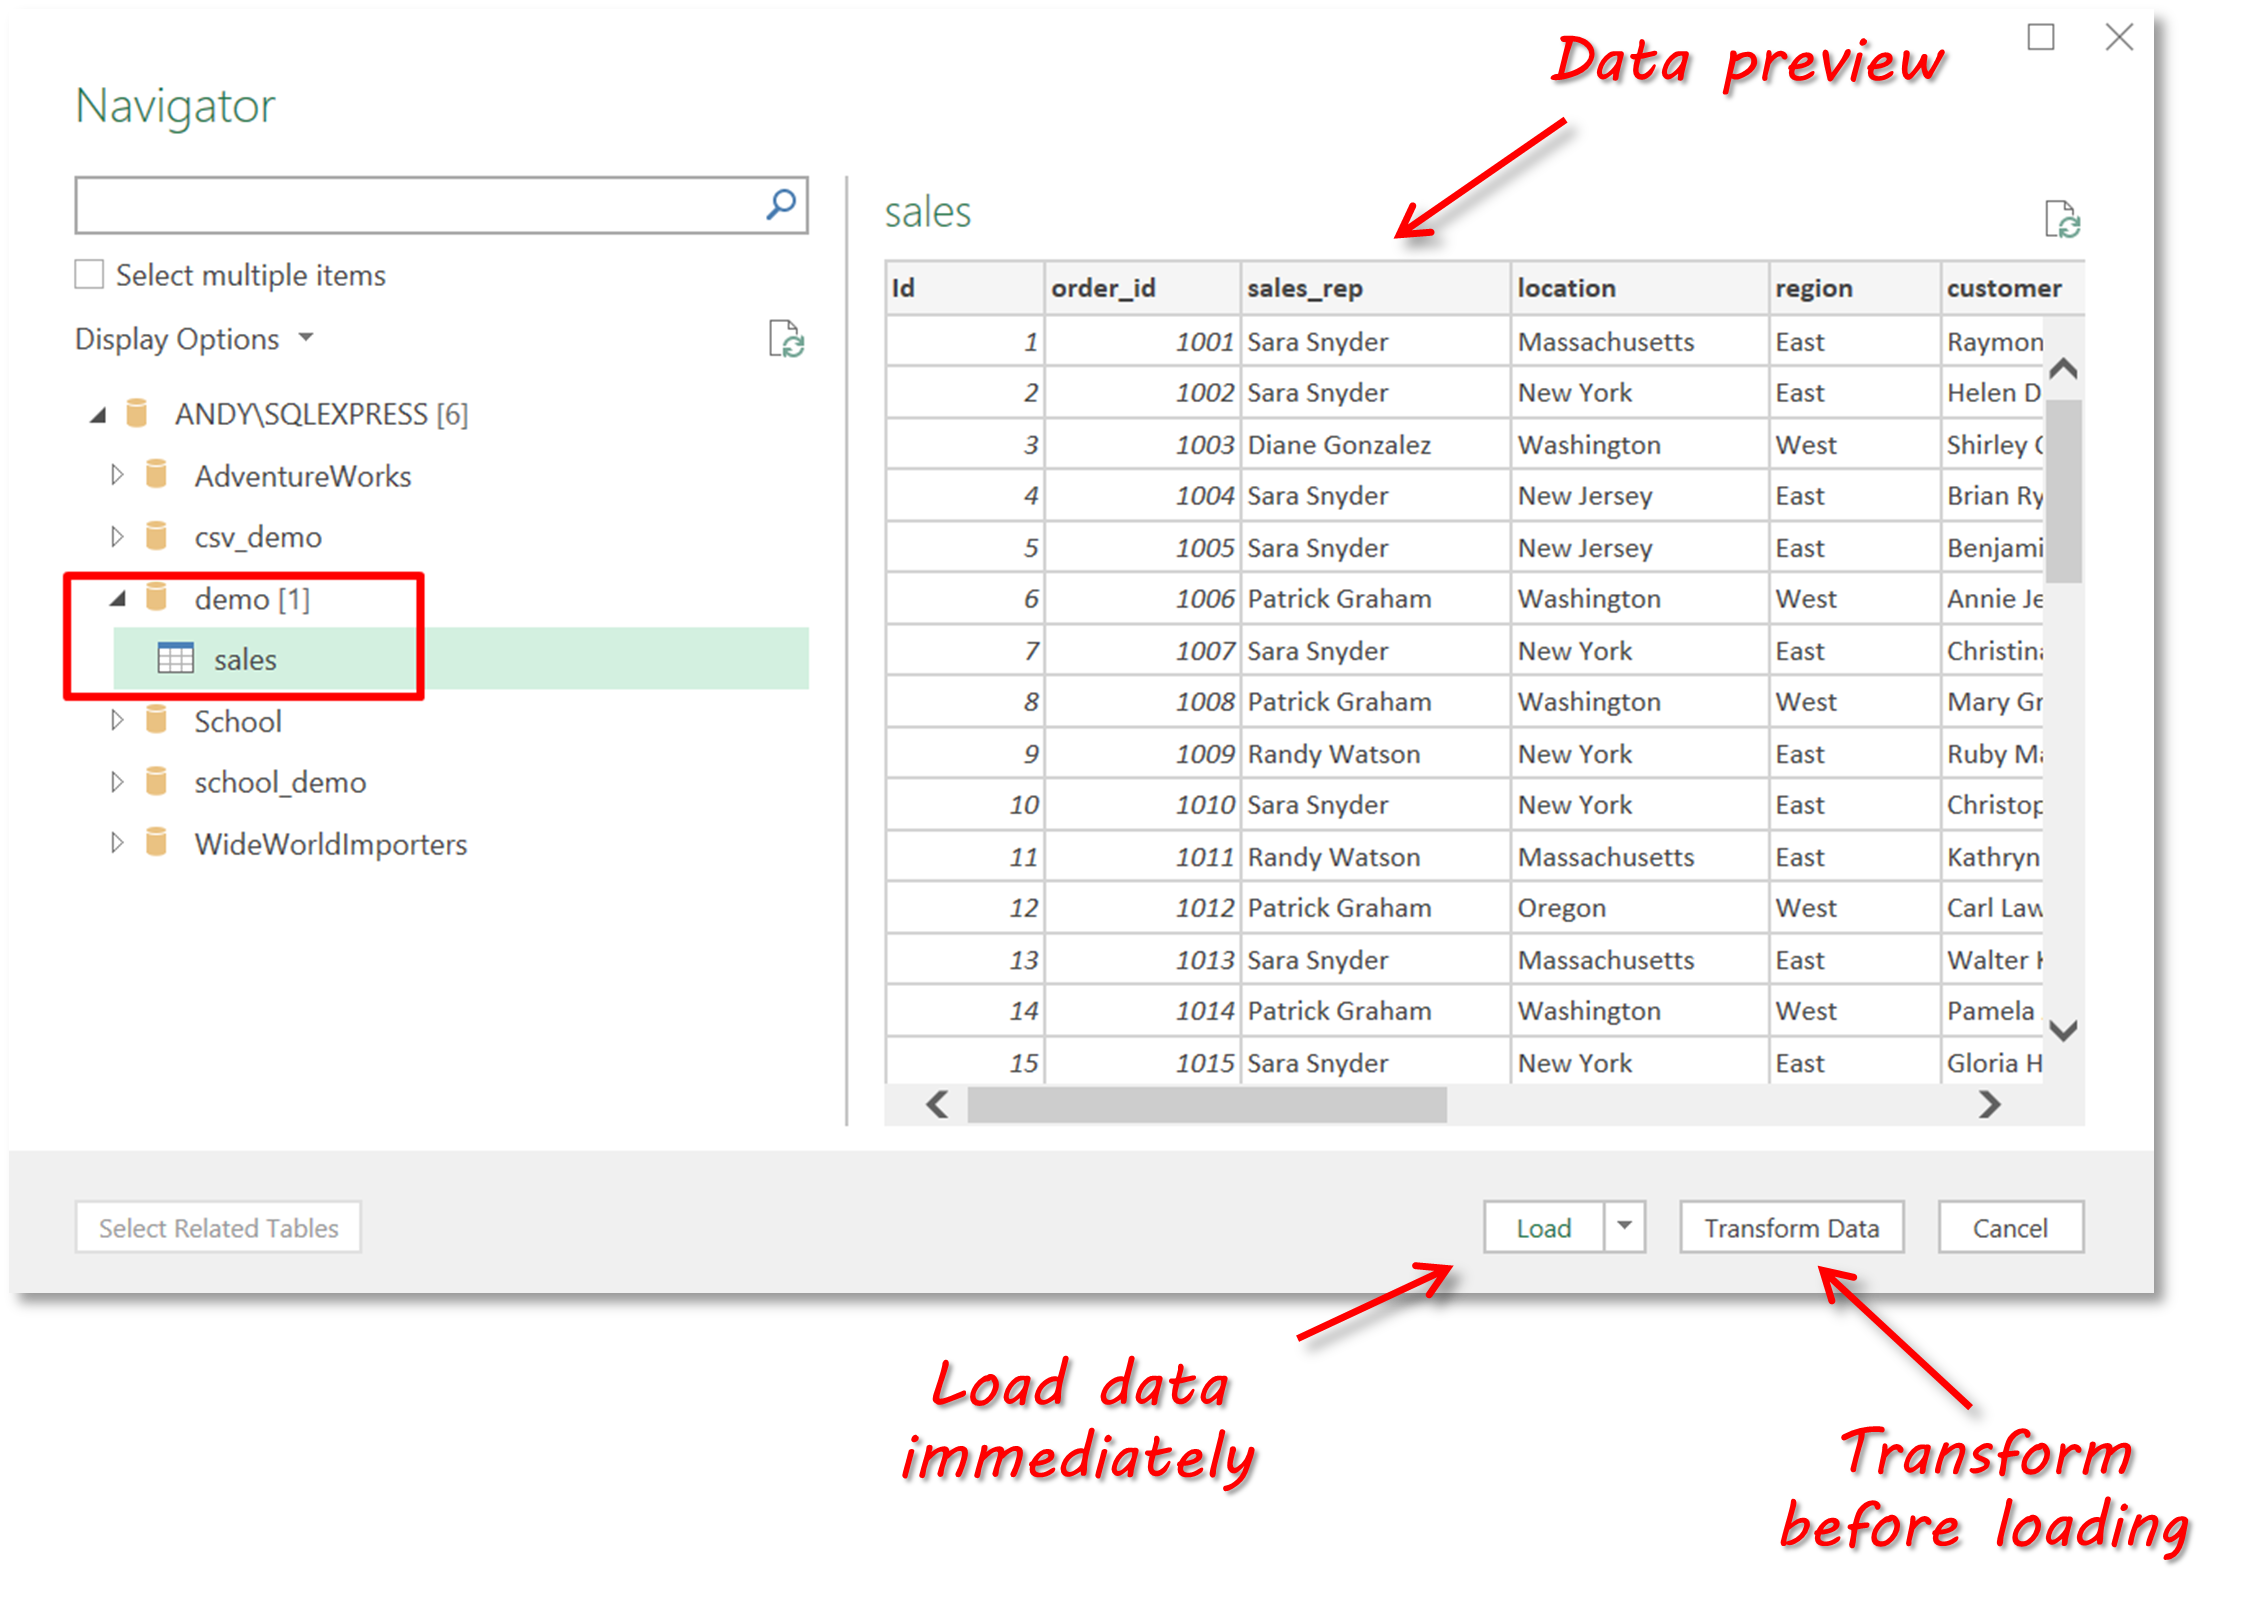
The next screen allows you to navigate through the databases and tables on the database server that you specified. Click on the ‘demo’ database to expand it and then click on the ‘sales’ table. The data for the selected table is displayed in the right-hand window. We could now click the ‘Load’ button to get the data into Excel immediately. Alternatively, we can click on ‘Transform Data’ to perform transformations on the data (eg change data types, clean up some data, perform computations). For this example, we’re just going to load the data as it is, so go ahead and click ‘Load’.
The data is now exported from the table in SQL Server and loaded into a new sheet in Excel.
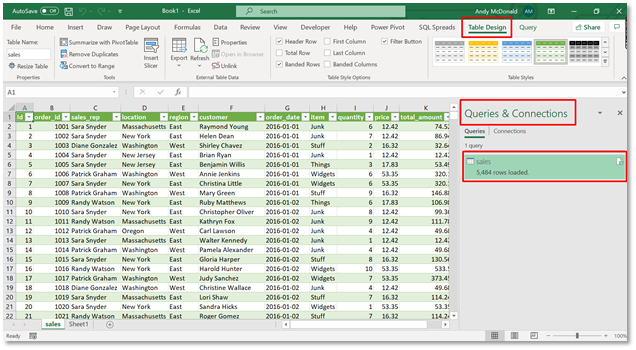
That is all we need to do to perform a simple export of a full table from SQL Server to Excel. Aside from the simple procedure we’ve described here, the Power Query data import wizards and tools provide ways to ‘shape’ the data from external sources. For example, you can remove a column, change a data type, merge tables to meet your specific needs.
Method (3): Exporting using SQL Spreads Add-In for Excel
If you don’t already have the SQL Spreads Add-In for Excel installed, you can download a copy here .
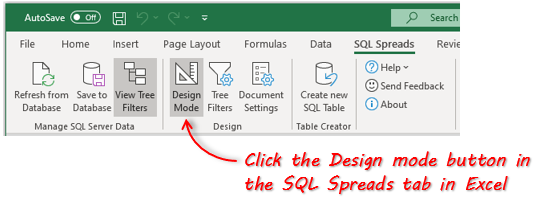
Once SQL Spreads is installed, you’ll see that it has been added as a new ribbon tab; go here and click the Design Mode button.
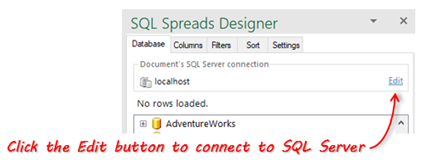
In the SQL Spreads Designer panel on the right side, click the Edit button to open the SQL Server connection dialog.
Enter the name of your SQL Server into the SQL Server name field. You also need to choose an authentication method: Windows-login (Windows Authentication) or SQL Server Authentication (using a name and password set up in SQL Server). Windows authentication is the more secure of the two options.
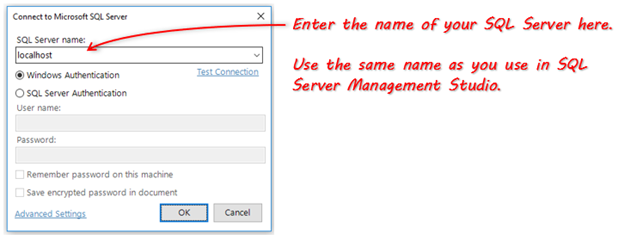
Click OK. SQL Spreads will try to connect to the database. If the connection is successful, your databases will show up in the SQL Spreads Designer panel.
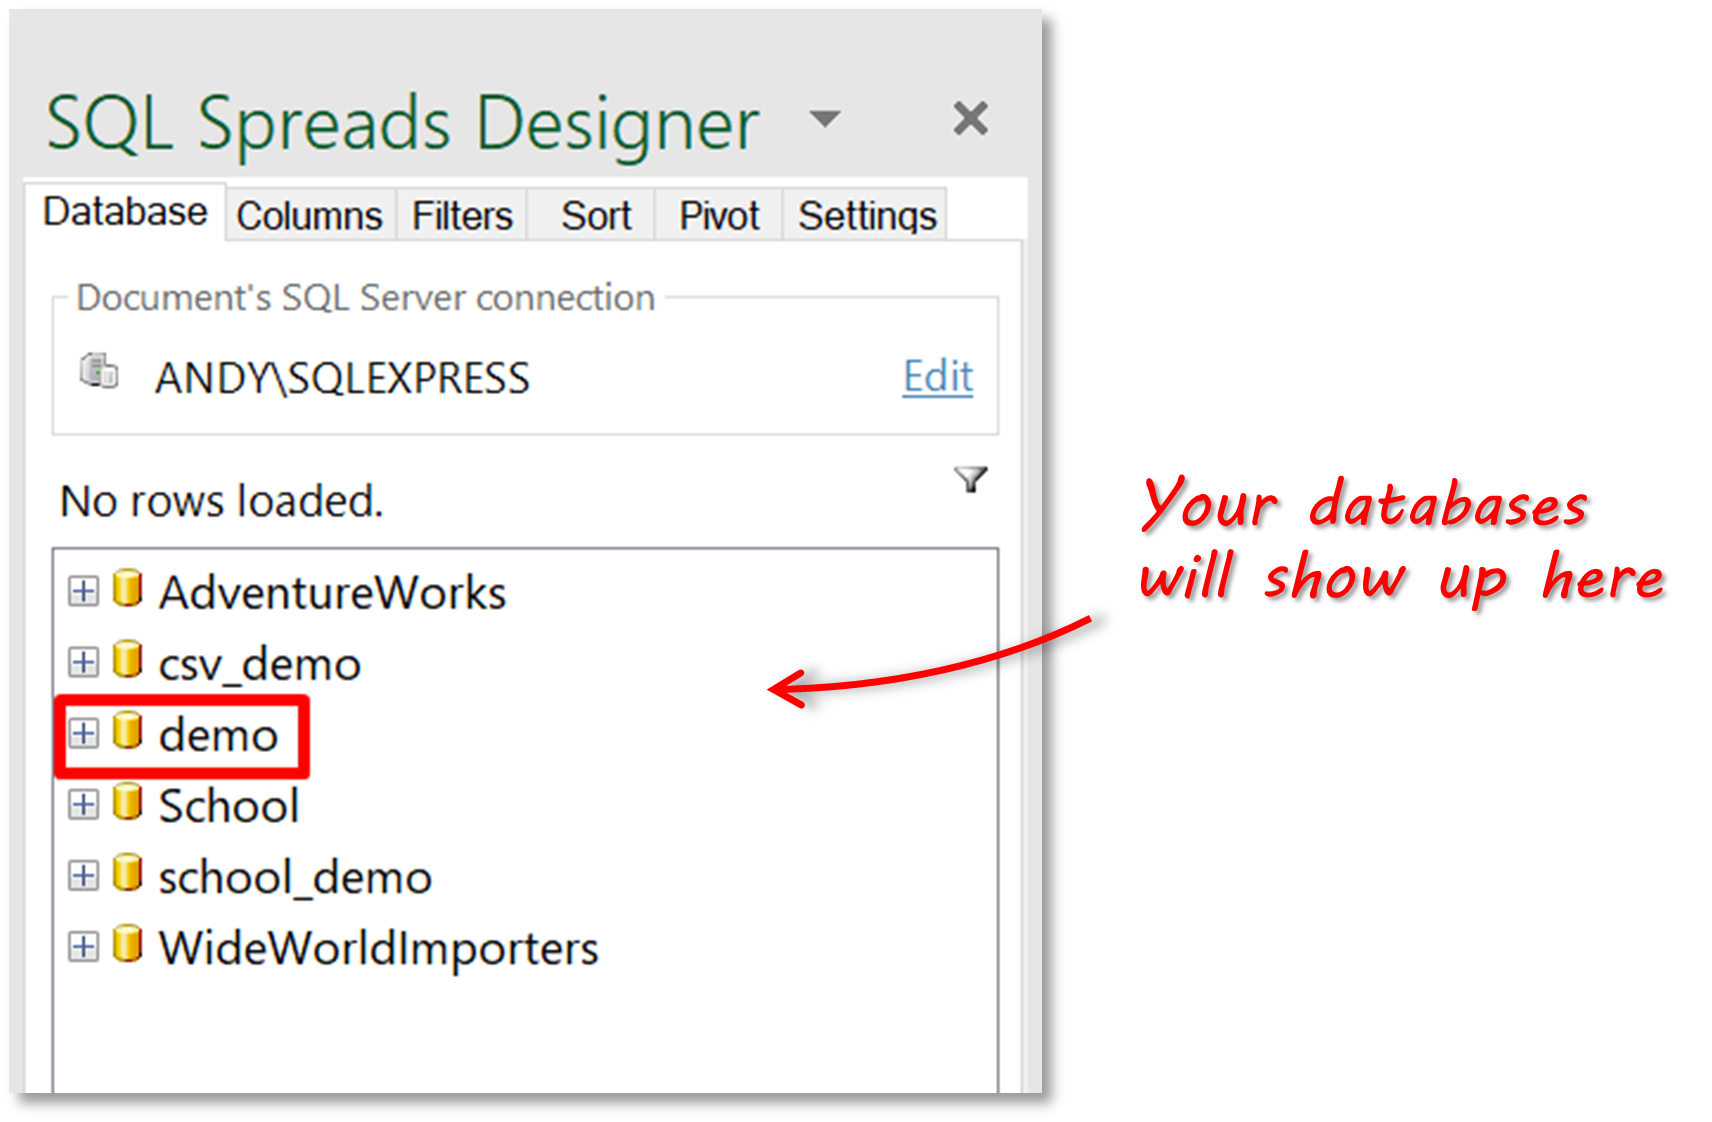
We can now expand the demo database and select the sales table.
When you click on the table, the data is immediately exported from SQL Server and copied to a sheet called ‘sales’ in Excel.
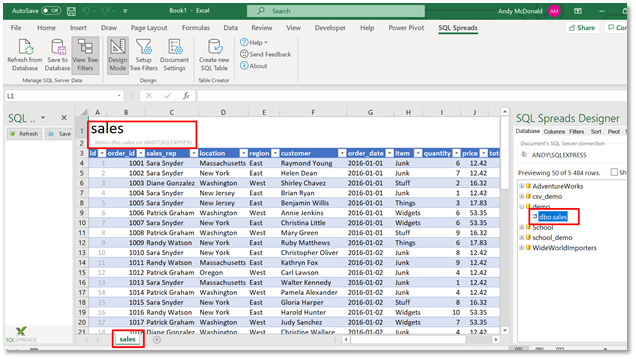
That’s it! We’ve managed to export data from SQL Server to Excel with just a couple of clicks.
There are several more options available to us in the SQL Spreads Designer. For example, we can:
- filter the data that is exported from SQL Server
- set whether certain columns are displayed and/or read-only
- use a look-up value to display text instead of an id for a column
- sort data
- make updates in Excel and save changes to SQL Server
There is more information on these features in the SQL Spreads knowledgebase here .
Summary
Being able to export data from SQL Server to Excel is a common requirement in most businesses. We’ve looked at three methods for performing this day-to-day task. The first uses the SQL Server Import and Export Wizard, which is native functionality in SQL Server. The second method uses the native ‘Get & Transform’ tools in Excel. The third uses the SQL Spreads Add-In for Excel.
So which method should you use?
If you normally work with databases, and SSMS is your second home, you’ll probably feel that the SQL Server Import and Export Wizard is the best option for you. If you are an Excel user, then it makes sense to work from within Excel itself to export data from SQL Server. Both of the two Excel options that we’ve looked at are robust and easy to use, but SQL Spreads has a distinct advantage because it allows users to make updates to data directly in Excel and then save the data back to SQL Server. This is a huge advantage for those organizations that like the best of both worlds: the ease of use and familiarity of Excel, with the power and data integrity associated with SQL Server.
Try SQL Spreads to see how quick and easy it is to export data from SQL Server to Excel; download a free trial version today.
*This article was originally published on August 26, 2021 and was updated on July 4, 2022 to include some new screenshots.
Article by
Andy McDonald
Andy has worked 20+ years in the Engineering, Financial, and IT sectors with data analysis and presentation using tools such as SQL Server, Excel, Power Query and Power BI.
Writes for SQL Spreads about Excel and SQL Server and how to tie those two together.
Как сделать экспорт таблиц из .sql в excel?
У меня на компьютере есть файл test.sql, мне необходимо перевести из него данные в excel’евские таблицы. Как это сделать?
- Вопрос задан более трёх лет назад
- 825 просмотров
Комментировать
Решения вопроса 0
Ответы на вопрос 3
Boris Köln @BorisKorobkov Куратор тега MySQL
Web developer
Загрузить дамп в БД, потом экспортировать в csv
Ответ написан более трёх лет назад
Комментировать
Нравится 1 Комментировать

Кое-что умею
Ответ написан более трёх лет назад
Комментировать
Нравится Комментировать
Ещё подскажу, может кому пригодится. Если вы находитесь в MySql Workbench и хотите просто использовать Ctrl+С (копирование столбца или столбцов после выделения) и вставку Ctrl+V в Excel. То сможете это сделать только, если у вас в Excel открыт csv файл. Поэтому перед копированием в excel изначально создайте новый лист сохраните его в формат csv, например в csv (разделители) и затем копируйте из MySql в Excel.
При этом Google Docs позволяет сразу вставлять из MySql. Т.е. в MySql выделяете столбец или всю таблицу, копируете и вставляете в Excel в Google Docs.
Ответ написан более трёх лет назад
Комментировать
Нравится Комментировать
Ваш ответ на вопрос
Войдите, чтобы написать ответ

- Excel
- +1 ещё
Как посчитать количество дней в работе в Excel?
- 1 подписчик
- 59 минут назад
- 32 просмотра
Как из ms sql экспортировать данные в excel?
Есть ms sql server 2012 и есть excel 2007 надо экспортировать данные в excel. стандартное средство импорта экспорта данных не дает выбрать на втором шаге excel. только базы данных.
Нашел на msdn видео как через visual studio это сделать. но там он старый а сейчас только 2012 есть. все прошел по шагам, затык на последнем моменте. имена столбцов в excel прописывает а дальше не хочет.
- Вопрос задан более трёх лет назад
- 12418 просмотров
1 комментарий
Оценить 1 комментарий
Как выбрать 1 млн. записей из бд, записать в Excel и не упасть с OutOfMemoryError
Совсем недавно мне была поставлена задача, написать сервис, который будет заниматься всего лишь одной, но очень емкой задачей – собирать большой объем данных из базы, агрегировать и заполнять все это в Excel по определенному шаблону. В процессе поиска лучшего решения было опробовано несколько подходов, решены проблемы, связанные с памятью и производительностью. В этой статье я хочу поделиться с вами основными моментами и этапами реализации данной задачи.
1. Постановка задачи
В связи с тем, что мне нельзя разглашать подробности ТЗ, сущности, алгоритмы сбора данных и т. д. Пришлось придумать что-то аналогичное:
Итак представим, что у нас есть онлайн чат с высокой активностью, и заказчик хочет выгружать все сообщения, обогащенные данными о пользователе, за определенную дату в Excel. В день может копиться более 1 миллиона сообщений.
У нас есть 3 таблицы:
- User. Хранит имя пользователя и его некий рейтинг (не важно откуда он берется и как считается)
- Message. Хранит данные о сообщении – Имя пользователя, ДатуВремя, Текст сообщения.
- Task. Задача на формирование отчета, которую создает заказчик. Хранит ID, Статус задачи (выполнено или нет), и два параметра: Дату сообщения начало, Дату сообщения конец.
Состав колонок будет следующим:

В Excel Заказчик хочет видеть 4 колонки 1) message_date. 2) name. 3) rating. 4) text. Ограничение по количеству строк 1 млн. Надо заполнить этими данными excel, а дальше заказчик уже будет работать с этими данными в екселе самостоятельно.
2. Задача понятна, начнем поиск решения
Так как в компании все стараются придерживаться единого стиля в разработке приложений, то и мне пришлось начать с самого обычного подхода, который используется во всех остальных микросервисах – это Spring + Hibernate для запуска приложения и работы с БД. В качестве БД используется Oracle, хотя использование любой другой СУБД будет плюс минус похожим.
Для старта приложения нам понадобится зависимость spring-boot-starter-data-jpa, которая объединяет в себе сразу Spring Data, Hibernate и JPA, все это нам понадобится для удобства работы с БД и нашими сущностями.
org.springframework.boot spring-boot-starter-data-jpa 2.4.5
Для тестирования добавим spring-boot-starter-test
org.springframework.boot spring-boot-starter-test test
И еще нам нужен сам драйвер для подключения к БД
com.oracle.database.jdbc ojdbc10 19.10.0.0
Далее нам нужно добавить некоторые настройки конфигурации. У нас будет один метод, который будет ходить в таблицу TASK, искать задачу в статусе “CREATED” и, если такая задача существует, то запускать генерацию отчета с параметрами. Предполагается, что генерация отчета может быть долгой, поэтому наш метод будет запускаться по расписанию в два потока асинхронными процессами. Так же для Spring Data укажем наш репозиторий для поиска соответствующих сущностей. Класс конфигурации будет выглядеть следующим образом:
package com.report.generator.demo.config; import org.springframework.boot.autoconfigure.condition.ConditionalOnProperty; import org.springframework.context.annotation.Bean; import org.springframework.context.annotation.Configuration; import org.springframework.context.annotation.PropertySource; import org.springframework.data.jpa.repository.config.EnableJpaRepositories; import org.springframework.scheduling.TaskScheduler; import org.springframework.scheduling.annotation.EnableAsync; import org.springframework.scheduling.annotation.EnableScheduling; import org.springframework.scheduling.concurrent.ThreadPoolTaskScheduler; @Configuration @EnableScheduling @EnableAsync @EnableJpaRepositories(basePackages = "com.report.generator.demo.repository") @PropertySource() @ConditionalOnProperty( value = "app.scheduling.enable", havingValue = "true", matchIfMissing = true ) public class DemoConfig < private static final int CORE_POOL_SIZE = 2; @Bean(name = "taskScheduler") public TaskScheduler getTaskScheduler() < ThreadPoolTaskScheduler scheduler = new ThreadPoolTaskScheduler(); scheduler.setPoolSize(CORE_POOL_SIZE); scheduler.initialize(); return scheduler; >> Класс генерации отчетов содержит в себе @Scheduled метод, который раз в минуту ищет Task и, если находит, то запускает генерацию отчета с параметрами из этой таски.
@Async("taskScheduler") @Scheduled(fixedDelay = 60000) public void scheduledTask() < log.info("scheduledTask is started"); Task task = getTask(); if (Objects.isNull(task)) < log.info("task not found"); return; >log.info("task found"); generate(task); >
Класс стартер приложения не имеет ничего примечательного, весь код можно посмотреть на GitHub.
3. Выборка данных из БД
Т.к. в компании повсеместно используется Hibernate было решено использовать его. Добавлено entity MessageData с необходимым набором полей (id, name, rating, messageDate, test). Первой попыткой выбрать необходимые данные была попытка в лоб – выгрузить все в List с помощью простого метода:
List findAllByMessageDateBetween(Instant dateFrom, Instant dateTo);А дальше уже в цикле создавать объекты MessageData и обогащать их недостающими данными. Было очевидно, что данных подход в корне не верный и выгружать сразу миллион записей в List как минимум медленно. Но для эксперимента и замера скорости работы проверить хотелось, чтобы потом сравнить с другими вариантами. Но в результате данный набор записей выгружался около 30 минут после чего было получено OutOfMemoryError и на этом эксперимент завершился.
Даже если бы пользователь задал узкие рамки в параметрах и нам бы удалось выбрать все в один List, то дальше мы бы столкнулись со следующей проблемой – для заполнения всех необходимых колонок нужно было бы собирать id пользователей, идти снова в базу, получать их имена и рейтинги, и заполнить уже с полными данными. Сложность такого алгоритма вырастала в разы. Было понятно, что выборку надо производить по частям и переложить все возможные действия с данными на сторону бд. Чтобы не выбирать все разом и, чтобы не городить велосипедов, было решено использовать ScrollableResults. Это позволяет нам получить ссылку на курсор и итерироваться по результатам с определенным шагом. Далее пришлось переписать запрос так, чтобы он возвращал сразу все необходимые данные уже после всех джойнов, объединений, группировок и т. д.
Следующий вопрос – где хранить сам текст запроса. Это был не простая ситуация т.к. в действительности количество таблиц, которые участвовали в запросе было около десяти, количество джойнов и всяческих группировок было огромным, в результате чего текст запроса вышел на 200+ строк после ревью всевозможных коллег и утверждении самим тех лидом. Хранить такой запрос в java коде не хотелось, плюс в нем были захардкожены некоторые константы в условиях и светить ими в общем репозитории было бы неправильно. Для решения всех этих вопросов мне на помощь пришла идея использовать view. Весь текст запроса прекрасно туда вписывался, плюс на выходе мы получаем готовую сущность, с которой может работать hibernate как с обычной entity.
По началу все выглядело нормально, запрос на выборку 1 млн таких строк выполнялся за разумные 10 мин. или около того. Немного больше, чем хотелось бы, но заказчика это устраивало. Однако в процессе тестирования обнаружился серьезный минус такого подхода – когда мы выбираем 1 млн записей, запрос выполняется 10 минут, но когда мы хотим отчет по короче и указываем в параметрах границы даты поуже – у нас запрос так же выполняется 10 минут, но в результате мы можем получить хоть 1 запись, хоть миллион. Суть в том, что внутрь запроса view нельзя передавать параметры, мы можем только выполнить статический запрос и уже на результат наложить параметры. Поэтому не важно сколько будет в результате строк, в первую очередь будет выбрано все, что найдется в бд, а только потом будет применены параметры. Заказчику было все равно, его устраивало и то, что отчет с одной строкой будет формироваться практически за такое же время, что и отчет с 1 млн строк. Однако это излишне нагружало бд и было решено отказаться от этого варианта.
Оставался всего один вариант, который нам подходил – это хранимая в бд функция. В нее можно передавать параметры, она может вернуть ссылку на курсор и ее результат можно удобно маппить на нашу entity. Таким образом была описана функция, которая принимала на вход несколько параметров, и возвращала sys_refcursor, весь скрипт занял около 300 строк в реальности, а в упрощенном варианте здесь она выглядит так:
create function message_ref( date_from timestamp, date_to timestamp ) return sys_refcursor as ret_cursor sys_refcursor; begin open ret_cursor for select m.id, u.name, u.rating, m.message_date, m.text from message m left join users u on m.user_id = u.id where m.message_date between date_from and date_to; return ret_cursor; end message_ref;Теперь как ее использовать? Для этого отлично подходит @NamedNativeQuery. Запрос для вызова функции выглядит следующим образом: «< ? = call message_ref(?, ?) >«, callable = true дает понять, что запрос представляет собой вызов функции, cacheMode = CacheModeType.IGNORE для указания не использовать кэш, т. к. скорость работы нам не так критична, как затрачиваемая память, ну и в конце resultClass = MessageData.class для маппинга результата на нашу entity. Класс MessageData выглядит следующим образом:
package com.report.generator.demo.repository.entity; import lombok.Data; import org.hibernate.annotations.CacheModeType; import org.hibernate.annotations.NamedNativeQuery; import javax.persistence.Column; import javax.persistence.Entity; import javax.persistence.Id; import java.io.Serializable; import java.time.Instant; import static com.report.generator.demo.repository.entity.MessageData.MESSAGE_REF_QUERY_NAME; @Data @Entity @NamedNativeQuery( name = MESSAGE_REF_QUERY_NAME, query = "< ? = call message_ref(?, ?) >", callable = true, cacheMode = CacheModeType.IGNORE, resultClass = MessageData.class ) public class MessageData implements Serializable
Для того чтобы не использовать кэш было решено выполнять запрос в StatelessSession. Однако есть важная особенность: если попытаться вызвать namedQuery то hibernate при попытке установить CacheMode выдаст UnsupportedOperationException. Чтобы этого избежать необходимо установить два хинта:
query.setHint(JPA_SHARED_CACHE_STORE_MODE, null); query.setHint(JPA_SHARED_CACHE_RETRIEVE_MODE, null);
В итоге наш метод генерации имеет следующий вид:
@Transactional void generate(Task task) < log.info("generating report is started"); try ( StatelessSession statelessSession = sessionFactory.openStatelessSession() ) < ReportExcelStreamWriter writer = new ReportExcelStreamWriter(); Queryquery = statelessSession.createNamedQuery(MESSAGE_REF_QUERY_NAME, MessageData.class); query.setParameter(1, task.getDateFrom()); query.setParameter(2, task.getDateTo()); query.setHint(JPA_SHARED_CACHE_STORE_MODE, null); query.setHint(JPA_SHARED_CACHE_RETRIEVE_MODE, null); ScrollableResults results = query.scroll(ScrollMode.FORWARD_ONLY); int index = 0; while (results.next()) < index++; writer.createRow(index, (MessageData) results.get(0)); if (index % 100000 == 0) < log.info("progress <>rows", index); > > writer.writeWorkbook(); task.setStatus(DONE.toString()); log.info("task <> complete", task); > catch (Exception e) < task.setStatus(FAIL.toString()); e.printStackTrace(); log.error("an error occurred with message <>. While executing the task <>", e.getMessage(), task); > finally < taskRepository.save(task); >>
4. Запись данных в Excel
На данном этапе вопрос с выборкой данных из БД был решен и возник следующий вопрос – как теперь все это писать в excel так, чтобы это было быстро и не затратно по памяти. Первая попытка была самой очевидной – это использование библиотеки org.apache.poi. Тут все просто: подключаем зависимость
org.apache.poi poi-ooxml 5.0.0
Создаем XSSFWorkbook далее XSSFSheet, из него уже row и так далее. Ничего примечательного, примерный код ниже:
package com.report.generator.demo.service; import com.report.generator.demo.repository.entity.MessageData; import org.apache.poi.xssf.usermodel.XSSFCell; import org.apache.poi.xssf.usermodel.XSSFRow; import org.apache.poi.xssf.usermodel.XSSFSheet; import org.apache.poi.xssf.usermodel.XSSFWorkbook; import java.io.FileOutputStream; import java.io.IOException; import java.time.Instant; public class ReportExcelWriter < private final XSSFWorkbook wb; private final XSSFSheet sheet; public ReportExcelWriter() < this.wb = new XSSFWorkbook(); this.sheet = wb.createSheet(); createTitle(); >public void createRow(int index, MessageData data) < XSSFRow row = sheet.createRow(index); setCellValue(row.createCell(0), data.getMessageDate()); setCellValue(row.createCell(1), data.getName()); setCellValue(row.createCell(2), data.getRating()); setCellValue(row.createCell(3), data.getText()); >public void writeWorkbook() throws IOException < FileOutputStream fileOut = new FileOutputStream(Instant.now().getEpochSecond() + ".xlsx"); wb.write(fileOut); fileOut.close(); >private void createTitle() < XSSFRow rowTitle = sheet.createRow(0); setCellValue(rowTitle.createCell(0), "Date"); setCellValue(rowTitle.createCell(1), "Name"); setCellValue(rowTitle.createCell(2), "Rating"); setCellValue(rowTitle.createCell(3), "Text"); >private void setCellValue(XSSFCell cell, String value) < cell.setCellValue(value); >private void setCellValue(XSSFCell cell, long value) < cell.setCellValue(value); >private void setCellValue(XSSFCell cell, Instant value) < cell.setCellValue(value.toString()); >> Но такой подход оказался не очень оптимальным. Примерно 3 минуты потребовалось на выборку 1 млн строк из бд и запись их в excel. И в итоге приводил к OutOfMemoryError. Вот пример:
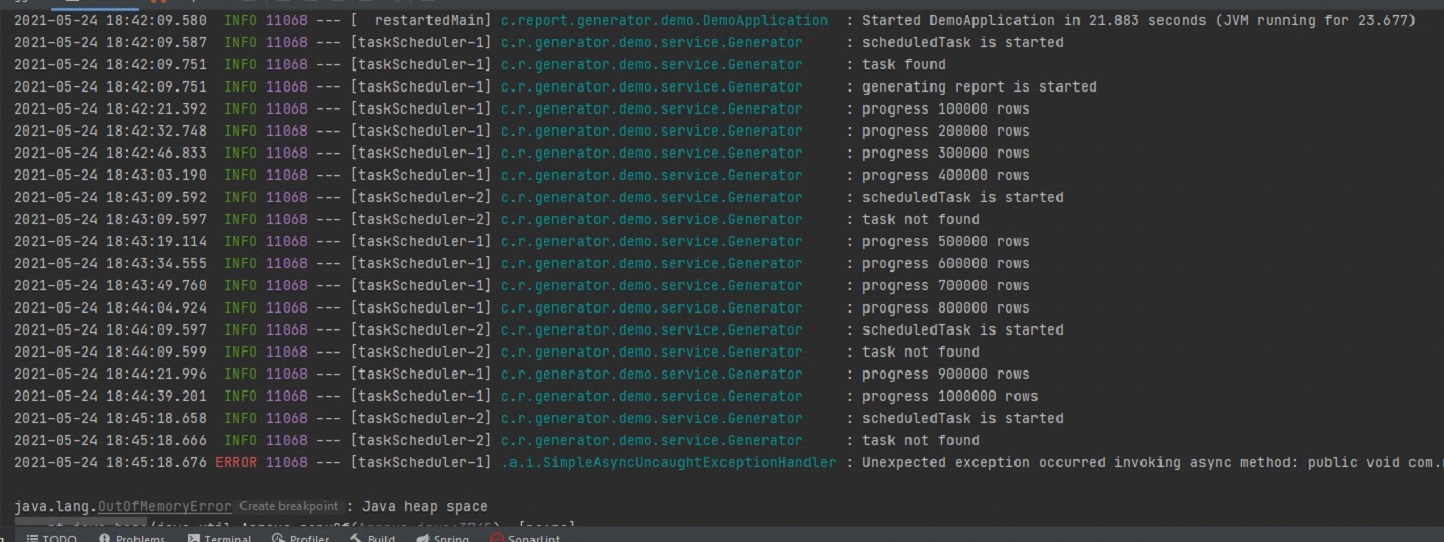
А когда я выполнял его на терминалке с выделенной оперативной памятью в 2Gb, то падал он с OutOfMemoryError примерно на 30% прогресса.
Грузить весь миллион строк в память в excel было так же плохой идеей, как и выгружать весь запрос в List, очевидно, здесь надо было использовать некий stream, но хоть какой-то годный пример google тогда мне не дал. Была попытка написать свое подобие I/O Stream для работы с excel, но мысль о том, что я пишу велосипед не давала мне покоя. В результате я стал изучать библиотеку org.apache.poi пристальней и оказалось, что там уже есть пакет streaming. В этом пакете уже есть весь необходимый набор классов для работы с большим объемом данных в excel. Оставалось только заменить все ключевые классы на аналогичные из пакета streaming и все:
package com.report.generator.demo.service; import com.report.generator.demo.repository.entity.MessageData; import org.apache.poi.xssf.streaming.SXSSFCell; import org.apache.poi.xssf.streaming.SXSSFRow; import org.apache.poi.xssf.streaming.SXSSFSheet; import org.apache.poi.xssf.streaming.SXSSFWorkbook; import java.io.FileOutputStream; import java.io.IOException; import java.time.Instant; public class ReportExcelStreamWriter < private final SXSSFWorkbook wb; private final SXSSFSheet sheet; public ReportExcelStreamWriter() < this.wb = new SXSSFWorkbook(); this.sheet = wb.createSheet(); createTitle(); >public void createRow(int index, MessageData data) < SXSSFRow row = sheet.createRow(index); setCellValue(row.createCell(0), data.getMessageDate()); setCellValue(row.createCell(1), data.getName()); setCellValue(row.createCell(2), data.getRating()); setCellValue(row.createCell(3), data.getText()); >public void writeWorkbook() throws IOException < FileOutputStream fileOut = new FileOutputStream(Instant.now().getEpochSecond() + ".xlsx"); wb.write(fileOut); fileOut.close(); >private void createTitle() < SXSSFRow rowTitle = sheet.createRow(0); setCellValue(rowTitle.createCell(0), "Date"); setCellValue(rowTitle.createCell(1), "Name"); setCellValue(rowTitle.createCell(2), "Rating"); setCellValue(rowTitle.createCell(3), "Text"); >private void setCellValue(SXSSFCell cell, String value) < cell.setCellValue(value); >private void setCellValue(SXSSFCell cell, long value) < cell.setCellValue(value); >private void setCellValue(SXSSFCell cell, Instant value) < cell.setCellValue(value.toString()); >> Теперь сравним скорость обработки данных с этой библиотекой:

Вся обработка заняла пол минуты и, самое главное, никаких OutOfMemoryError.
5. Итог
В результате удалось добиться максимальной производительности за счет использования хранимой функции, StatelessSession, ScrollableResults и использования библиотеки org.apache.poi из пакета streaming. При большом желании можно улучшить производительность еще, если написать все на чистом jdbc, может быть есть еще варианты, как, что и где можно улучшить. Буду рад услышать комментарии от более опытных в этом экспертов. В данном примере не учтено ограничение на 1 млн. строк, т. к. это простая формальность и для примера не очень важна. Для наполнения БД тестовыми данными был добавлен тестовый класс DemoApplicationTests. Весь код можно посмотреть в репозитории на GitHub.